
Synopsis: In this post and a preprint we show that a simple model can identify which chemist made a given molecule from structure alone, and that you can use authorship to make pretty good activity predictions without any knowledge of chemistry. In essence, we believe that modern AI chemistry methods somewhat resemble the image recognition field in 2010, which relied on a series of fragmented datasets that hampered generalized performance. This historical parallel may have lessons for the field of small molecule affinity prediction: the image community overcame these deficiencies in ways that could be translatable to the problem of drug design.
Paper: https://github.com/Leash-Labs/chemist-style-leaderboard/blob/trunk/clever_hans.pdf
Chemist style leaderboard: https://leash-labs.github.io/chemist-style-leaderboard/
Play Name That Chemist: https://leash-labs.github.io/chemist-style-leaderboard/#quiz
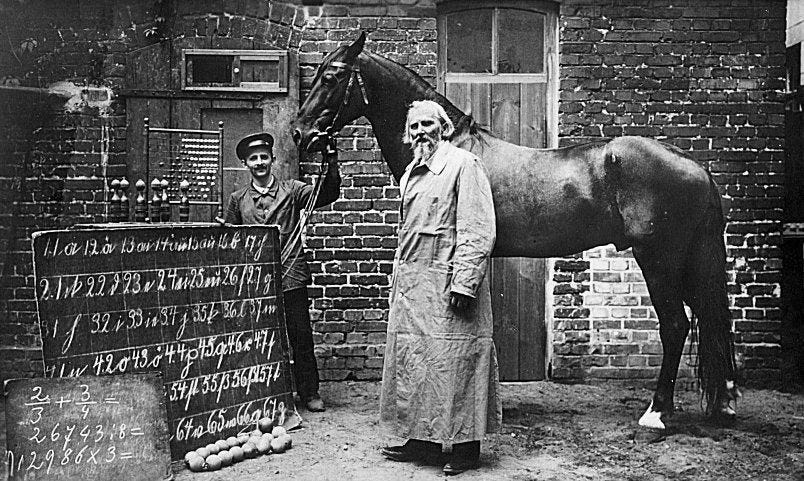
Wilhelm von Osten and Clever Hans, a horse seemingly capable of doing math. The horse would watch von Osten’s reactions as he stomped out the answer to a math problem, stopping when his owner unconsciously revealed the correct answer through posture and microexpressions.
In 2010, the Icelandic volcano Eyjafjallajokull erupted, blocking European air traffic long enough for a pair of bored object recognition researchers to think about the state of their field. (“Object recognition” meaning “can a computer identify the object in a given image”, ref 1). The result of this effort is a major classic in the field: Unbiased Look at Dataset Bias, by Antonio Torralba and Alexei A. Efros (ref 2).
At the time, if you were trying to teach computers how to look at images, you were working with collections of images taken of different objects. There were quite a few of these: Caltech-101 (ref 3), UIUC (ref 4), 3) MSRC (ref 5), Tiny Images (ref 6), ImageNet (ref 7), PASCAL VOC (ref 8), LabelMe (ref 9), SUNS-09 (ref 10), 15 Scenes (ref 11), Corel (ref 12), Caltech-256 (ref 13), COIL-100 (ref 14), and so on. As a researcher, you’d be staring at these images all day long, and you’d start to notice things about them.
This led to the bored researchers stuck during the volcano eruption to invent a game called Name That Dataset. If you were deep in the object recognition field and given a random picture, could you guess which of those datasets it came from?
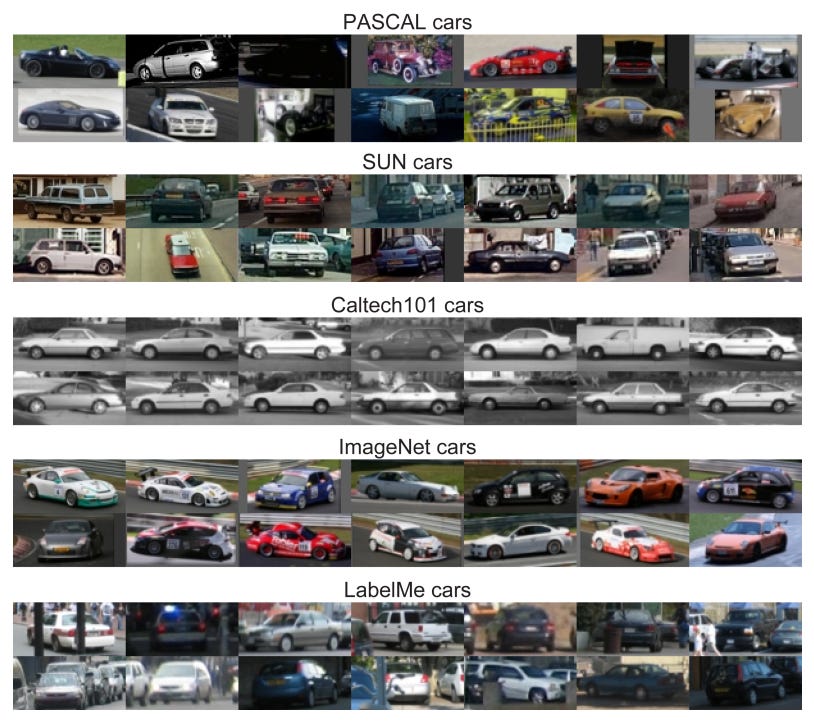
Figure 1. Distinctive cars from different image datasets. If one were given a new image that hewed to a collection’s general characteristics, assigning it to the correct dataset is pretty easy. Adapted from ref 2.
If you spent hours and hours staring at all these datasets, you’d get a feel for it. When the bored researchers surprised their teams with this game, they were intrigued by the results: “in our labs, most people got more than 75% correct.” Even a person not in the field can look at some of these images and see some obvious qualities that are common in one dataset and not others (fig 1).
So if a person can tell these apart, can a computer?
Yes.
A very simple classifier does a reasonable job at figuring out which dataset a given image comes from. By making a confusion matrix, the authors also showed that each dataset had its own signature style, a suite of characteristics that allow for good performance on this task.
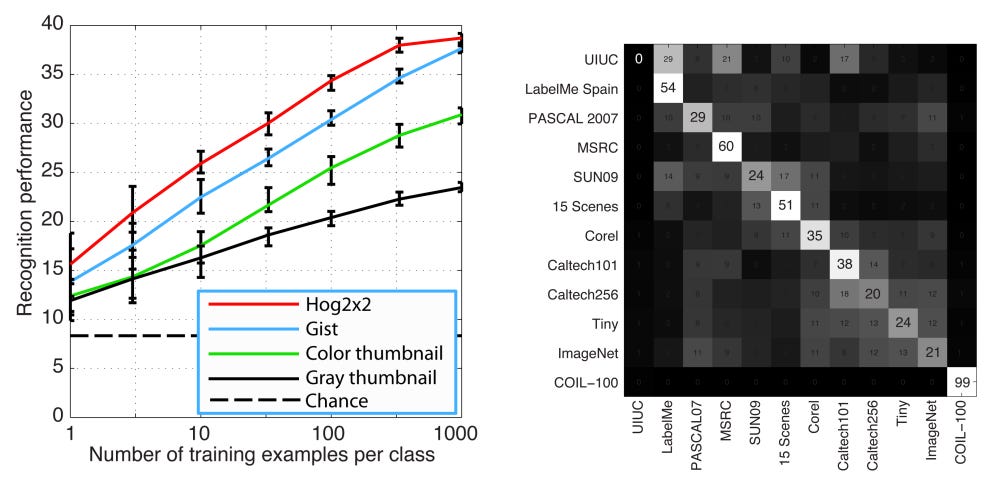
Figure 2. Prediction performance (left panel) in identifying the dataset a given image comes from and (right panel) confusion matrix of predictions across all the datasets. Adapted from ref 2.
Where do these signature styles come from?
They come from the human choices of the people who made the datasets. Right away you can see that whoever made ImageNet seems to like race cars, and the Caltech 101 team seems to like to take pictures from the side. Sometimes LabelMe cars have a trash can or some other object in the foreground. Even given what might seem like a simple job, “get as many labeled car pictures as we can to train models”, human creators have a difficult time resisting, or even identifying, their own subtle biases. The result is many different collections of images, that, if aggregated, can still be teased apart by an experienced human researcher.
The existence of this signature style hints at a deeper problem for image recognition progress that’s dependent on those datasets.
If whole datasets look different from each other, models have a hard time generalizing between them
Typically folks take a dataset and carve it into chunks, where they train their models on one chunk and then ask their models to predict on the other chunk. It’s simple to imagine doing this within one of these datasets and getting pretty good performance. But what if you train on one dataset and then predict on an entirely different dataset? In ref 2, it didn’t go so well. Depending on the object in the image, training on one dataset and testing on another might have a huge drop in performance, up to 78% (see ref 2, we really do encourage you to read the whole paper).
This situation resurfaced when a friend of ours looked at some molecules on a computer screen at Recursion in 2018. He was walking by and said something that blew our minds.
“That looks like a Stuart Schreiber molecule.”
What?
A human chemist can glance at a molecule and guess who made it? Does that mean a computer can do the same?
Turns out it can. It can very very easily.
This possibility had been haunting us for many years, and we finally did something about it. Last fall we downloaded all chemists from ChEMBL who we felt had been prolific (>30 publications, >600 molecules contributed) and all their molecules and then trained a very simple model to play Name That Chemist (fig 3, ref 15). Out of 1815 chemists, we had a top-5 accuracy of 60%.
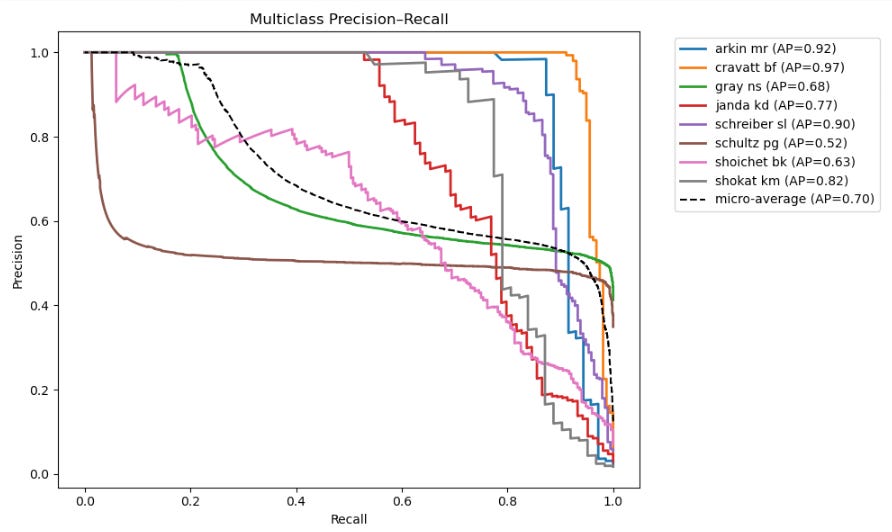
Figure 3. Precision-recall curve of predicting the creator of molecules from a handful of prominent chemists.
That is scarily good. 1815 choices and the model gets the correct one in its top 5 guesses more than half the time? There are not many classification problems that easy. If you make a confusion matrix, it looks suspiciously like those from fig 2 (see fig 4).
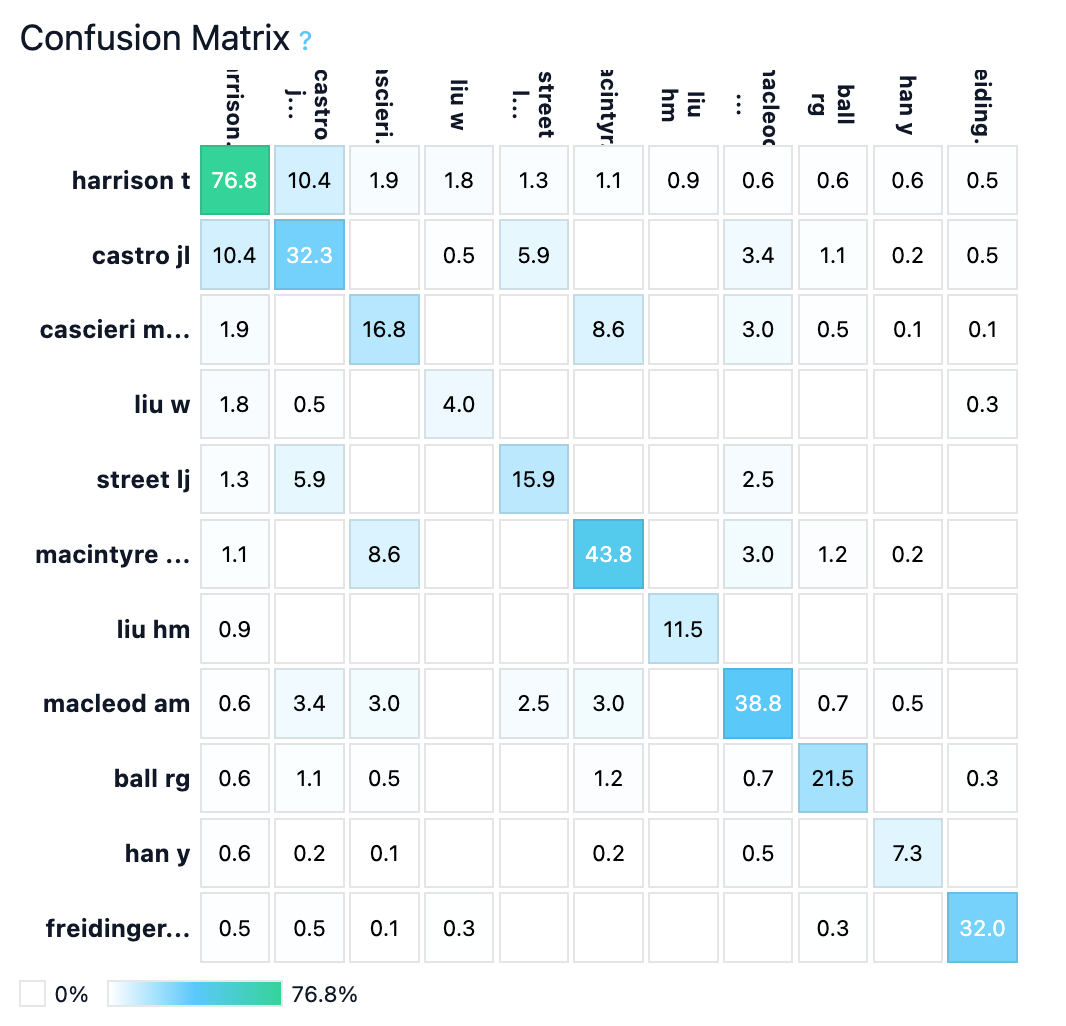
Figure 4. Confusion matrix of predicting chemistry author from molecules relative to Timothy Harrison, a chemist with a very distinctive style, and authors most similar to his style out of the 1815 authors we took from ChEMBL. Jose L. Castro, the most similar author out of 1814 of them, copublished with Harrison frequently and was in the same department. Since our models get confused most by coauthors, we suspect the existence of a mentor-to-mentee transfer of style, or perhaps a descent with modification. We wonder if one could even build academic phylogenies using these similarities.
If you look at Harrison’s molecules, you can see by eye that they are pretty distinctive (fig 5).
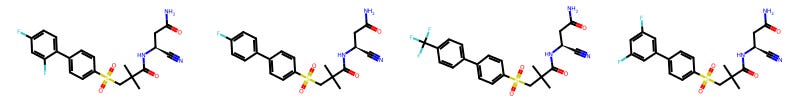
Figure 5. The most-distinctive molecules from Timothy Harrison.
Now compare these to another distinctive creator in our dataset, those of Carrie Haskell-Luevano (fig 6).
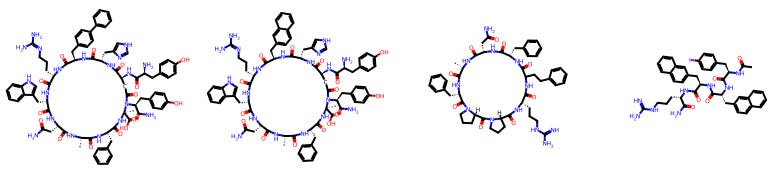
Figure 6. The most-distinctive molecules from Carrie Haskell-Luevano.
These two sets of molecules are very different from each other and easy to discriminate, even by someone without chemistry training. We built a whole leaderboard for you to examine the distinctiveness of these 1815 chemists. We also built a Name That Chemist game for you to try yourself. Enjoy!
If chemist signature style is associated with problems similar to those of image taker signature style, we might expect cross-dataset performance to suffer, and we have shown this is so (ref 16). But an even more insidious problem hides in there: while image takers from different groups often share the same objects (e.g. cars) in their images, chemist do not have any such motivation to use their chemistry to modulate the same protein targets.
If a model can identify a chemical’s creator, can it predict molecule performance?
We had a hunch that creators had favorite targets. One possibility is that models could guess their creator and use that information to guess molecule activity against a target the creator had studied (as compared to ones she had not). This scenario predicts that one could represent molecules not with molecule descriptors - no chemical formulas, no SMILES, no ECFPs - but instead solely with the probabilities of authorship, and train a model to identify if they were active against a given target.
This prediction is correct.
For ChEMBL, authorship probabilities are just about as good as molecular descriptors in our hands (figure 7).
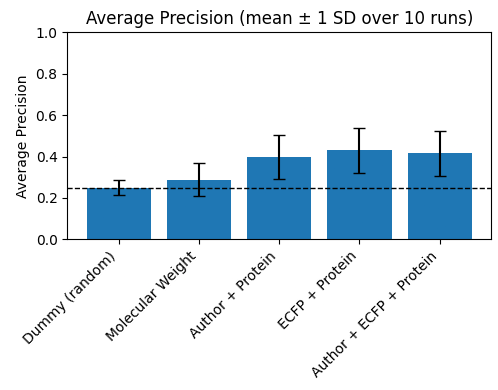
Figure 7. Predicting activity of molecules from prolific authors in ChEMBL using different feature sets.
To emphasize: a model trained on huge amounts of public data but not given any way to represent actual chemistry is able to predict small molecule activity almost as well as a model with knowledge of chemical structure. We suspect that the ability to discriminate authorship is a profound source of data leakage when trying to test and evaluate models on data sources like this.
For these results, and a lot more, please see our manuscript “Clever Hans in Chemistry: Chemist Style Signals Confound Activity Prediction on Public Benchmarks” (ref 15).
How about stage of development?
One dataset we wish we had includes how far along the medicinal chemistry journey a particular molecule might be. As researchers grow more confident in a chemical series, they’ll start putting more work into it, and this often includes more and more baroque modifications: harder synthesis steps, functional groups further down the Topliss tree, that kind of stuff. Molecular weight alone can be a great activity predictor: it tied for first place in CASP16 (figures 8-9 in ref 17, also fig 8 below). While the CASP16 affinity challenge was for two proteins, we can attest from internal work that molecular weight can be a great activity predictor across large numbers of proteins in public affinity binding data (our set in fig 7 doesn’t have as much molecular weight bias, so it fares poorly there).
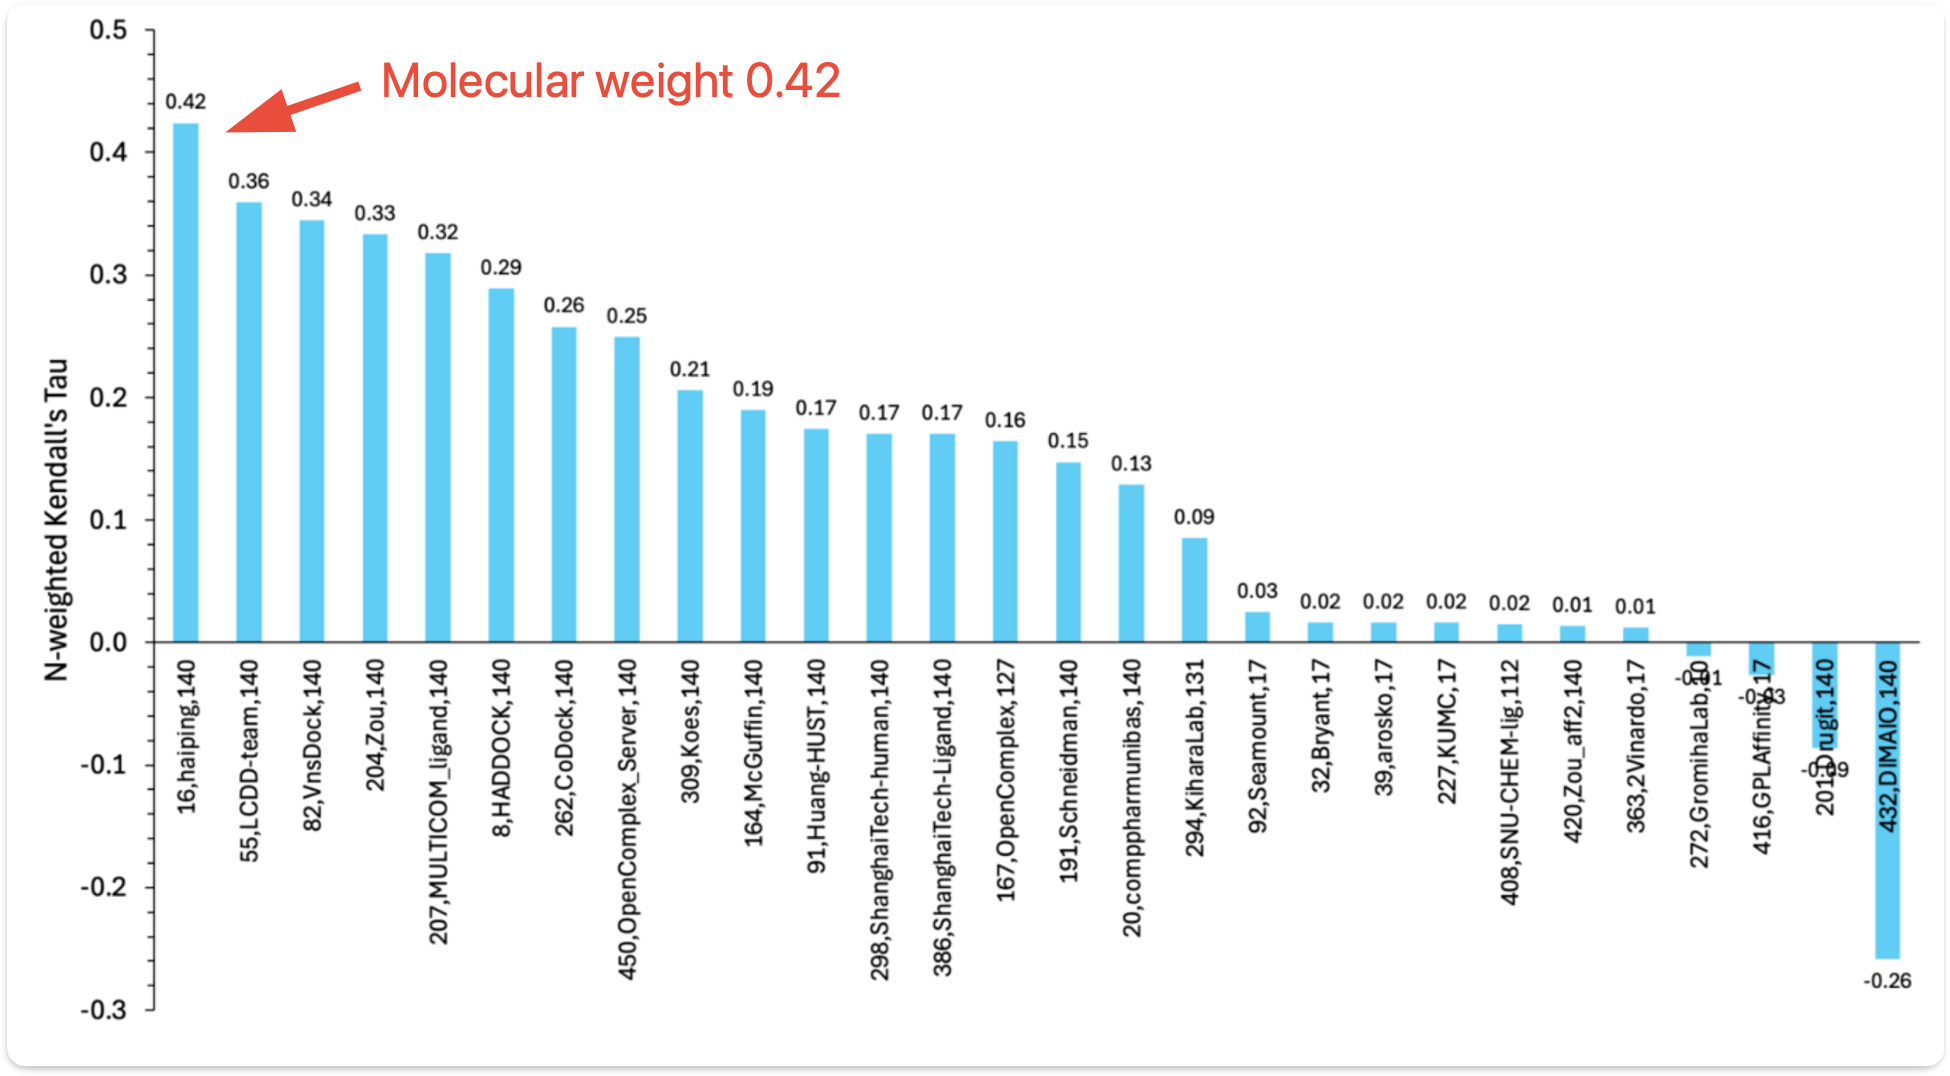
Figure 8. CASP16 affinity prediction results. We have added the baseline molecular weight model’s performance to the plot reporting contestant performance.
Where do we go from here? Ask the image people
At the end of Unbiased Look at Dataset Bias (ref 2), the authors offer some suggestions to the object recognition field. It is not an exaggeration to say in the 15 years since that work, object recognition in images has gotten very good. It’s so good that the flagship competition, the ImageNet Large Scale Visual Recognition Challenge, was retired in 2017 (ref 18).
We believe the field of predicting protein-ligand interactions bears a striking similarity to object recognition in 2010 in that different dataset creators have signature styles and that those styles stymie generalized prediction. The image people solved this signature style problem. How did they do it? We quote Torralba and Efros below and offer some thoughts.
Better negatives
As we have shown, having a rich and unbiased negative set is important to classifier performance.
Therefore, datasets that only collect the things they are interested in might be at a disadvantage, because they are not modeling the rest of the visual world. One remedy, proposed in this paper, is to add negatives from other datasets.
Folks are doing this already in chemistry, which we find heartening. The approach of using positives from other datasets (“synthetic decoys”) has been used effectively in boltz-2 training (ref 19) and elsewhere.
At Leash, we prefer the approach of identifying so-called “hard negatives”, or molecules that look very similar to one another but span an activity cliff for the target. We wrote about that strategy in ref 20. We believe screening with combinatorial libraries, with their large numbers of very similar molecules, can be a great method to enrich for such hard negatives.
More variation that preserves or changes outcome
The most well-known [capture] bias is that the object is almost always in the center of the image. Searching for “mug” on Google Image Search will reveal another kind of capture bias: almost all the mugs have a right-facing handle. Beyond better data sampling strategies, one way to deal with this is to perform various data transformations to reduce this bias, such as flipping images left-right, or jittering the image.
This form of bias leads to memorization from the models, and it’s clear to us models memorize proteins, which is a problem. That said, we’re not super convinced that one can reliably use digital data augmentation techniques to artificially boost an affinity dataset, because binding can be so cliffy. But there is another way: mutate the protein targets and physically rescreen, so that you can preserve the vast majority of the protein while keeping or destroying its binding profile. We’ve been doing this and are happy to report it works well (ref 21).
Explore more interaction variation in your own neighborhood
Datasets that are gathered automatically fare better than these collected manually.
The Name That Chemist exercise clearly shows individual chemists enjoy their own little playgrounds, and in their playgrounds we believe they play with a pretty small number of targets. This is okay! The Leash playground is pretty small too; we have a signature style of our own. But: we screen a lot more protein targets in that playground than most others do in theirs. We should hit 1000 proteins screened by January 2026, and we hope this dense sampling of our chemical space, coupled with extensive protein variation, will drive better and better performance. We have good reasons to believe this strategy is working: the more proteins in a family we screen, the better we can predict their binders close to our training set, and also further away.
